
Most Spark jobs run on wrong-sized machines with incorrect configs, leading to slow jobs, wasted spend, or both. We've found that we can get better performance at a lower price by continuously monitoring each job's performance and changing each job's instance type and worker count in real time.
Under the hood, this is a search problem: we're trying to find the lowest-cost configuration that meets your SLA. More generally, we map out the Pareto frontier of runtime vs. cost across compute configurations, and then move your job to it - the vast majority of jobs are not on the frontier today.
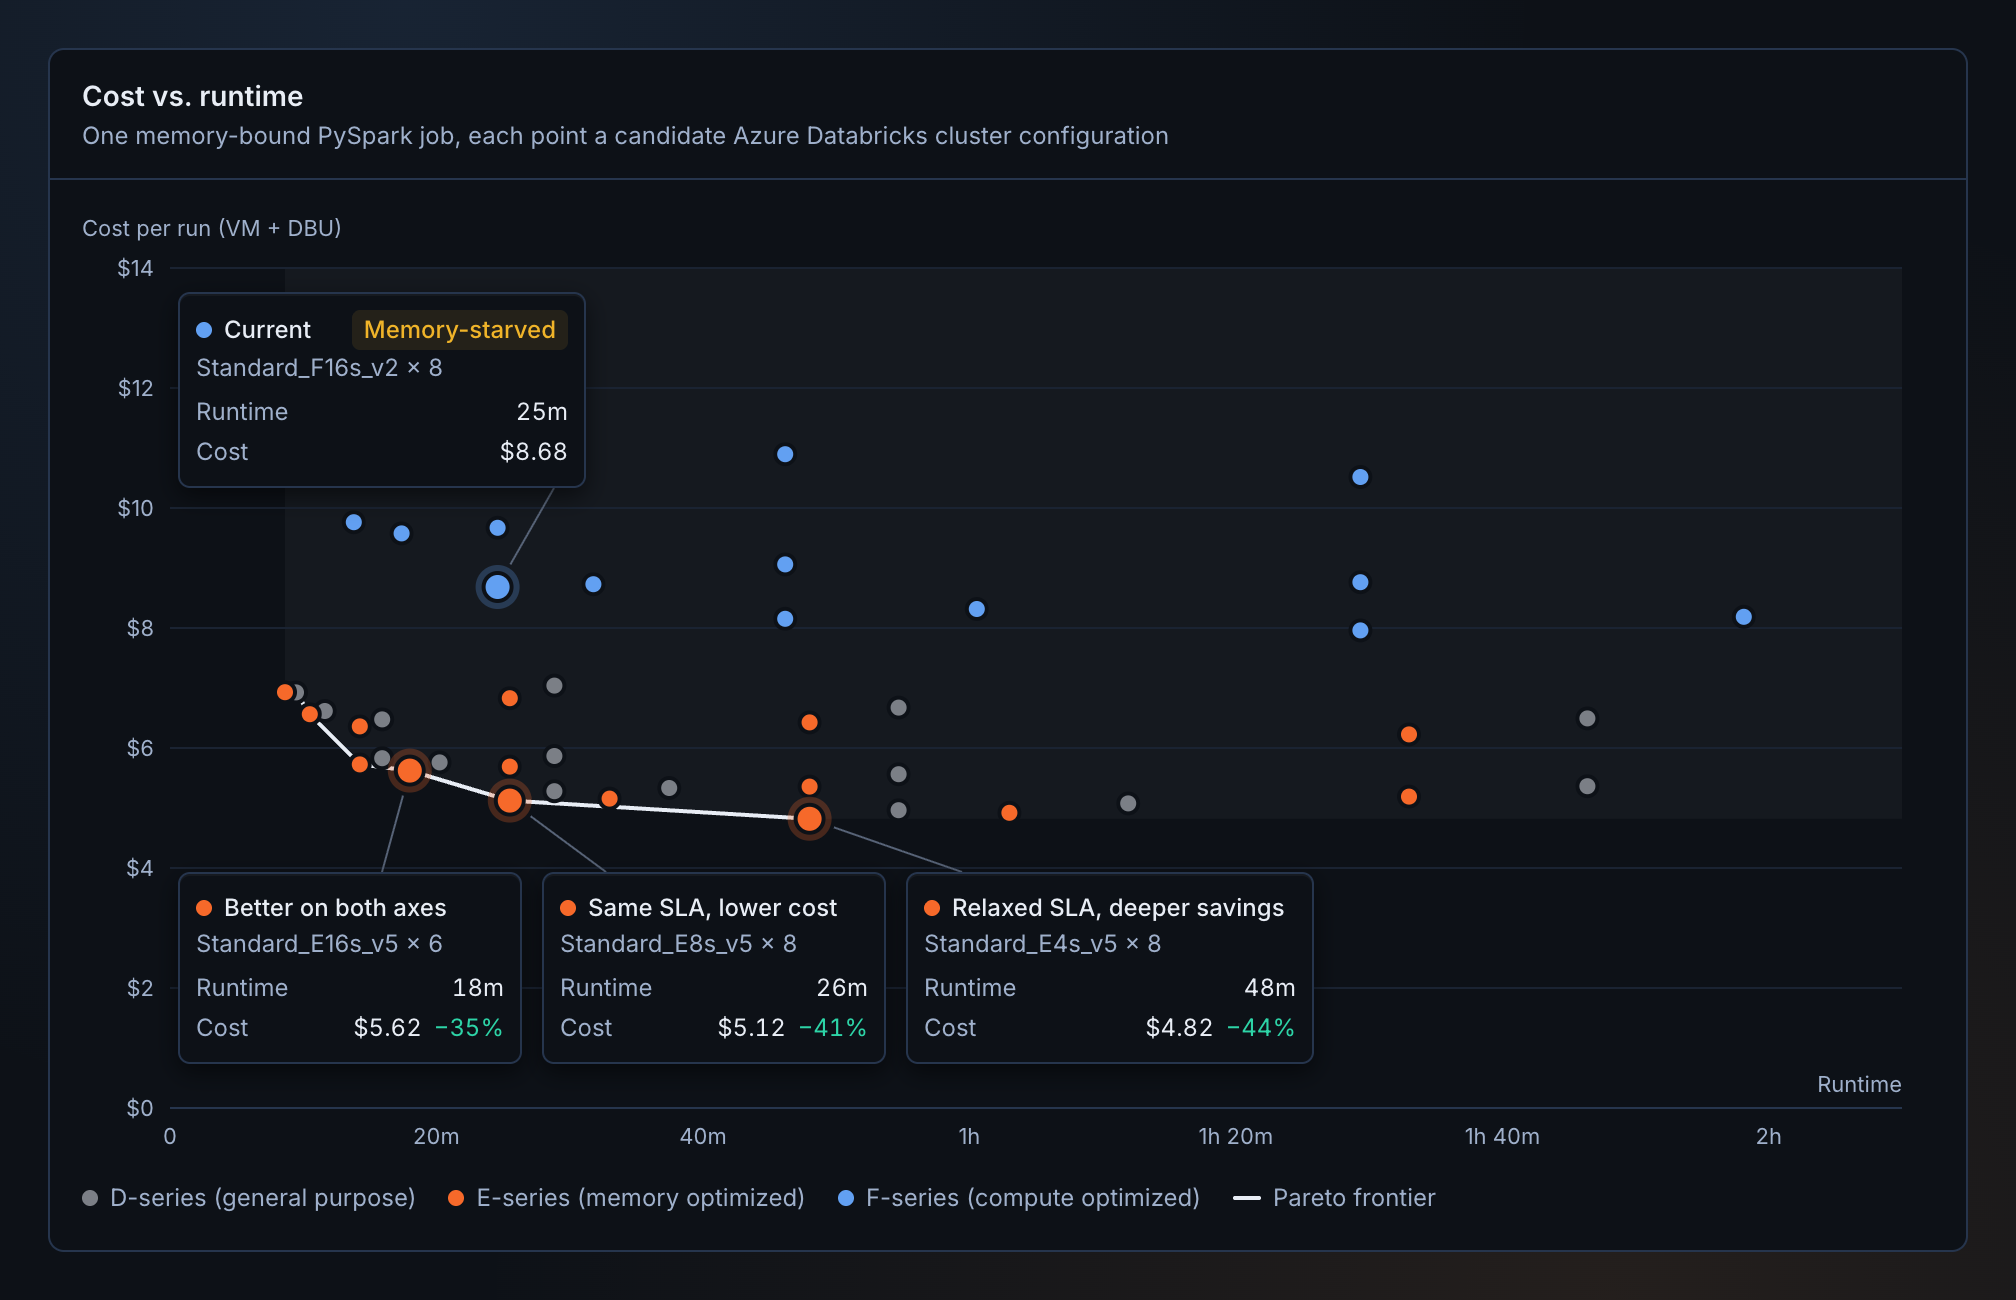
Testing every config would be slow and expensive; we use ML, alongside a small number of real samples, to understand the shape of your workload and winnow down the options.
We've found three consistent patterns for why job configurations are wrong:
- A job that was right-sized originally becomes memory- or CPU-starved as data grows. It fails intermittently, adds retry overhead, and costs more. We upsize it and stop the failures.
- A job runs on a much larger instance than it needs because somebody sized it “just in case.” We downsize it.
- The job is running on the wrong machine shape: it's starving for memory while CPU sits idle, or the reverse. We move it to a different instance family, which can lower cost and improve runtime.
The settings that control this, instance type and worker count, are usually chosen when somebody creates the job. They're rarely updated afterwards unless something OOMs or goes over SLA - and then jobs are usually upsized coarsely.
Our system reads each job’s CPU, memory, and I/O-wait traces from Databricks system tables. We use those usage patterns to estimate cost and runtime for candidate configurations, then choose the one that matches your SLA with built-in headroom. We then monitor jobs on an ongoing basis, handling retries and changing sizes as your jobs grow or shrink.
Users are seeing job costs go down from 35% to 85%. We're optimizing for cost, not runtime, but we've seen runtime drop by up to 60% as a side effect of moving jobs to machines that match their resource constraints.
Are you spending too much on Databricks Spark? Follow the instructions here to share metadata for a savings estimate, or reach out to us at databricks@espresso.ai.
Frequently Asked Questions

Never miss an update
Subscribe to our newsletter. Get exclusive insights delivered straight to your inbox.